What is Jev?
Jev is an AI model from TypeSafe AI that makes decisions using evidence and answer options supplied by an application. It returns choices, scores and probabilities that software can use directly to classify information, route tasks and select the next step in a workflow. It does not write text, produce code or explain itself.
TypeSafe calls Jev a System One model, after the fast, intuitive System 1 of Daniel Kahneman's Thinking, Fast and Slow. A developer might ask it which team should receive a support ticket, or whether a retrieved passage is relevant to a question. When the workflow then needs a reply or a code change, a generative model does that part. The two kinds of model sit side by side; Jev decides at the joints.
In one sentence
Your application supplies evidence and a defined question. Jev returns a typed decision with probabilities. Your code decides what happens next.
For someone building an AI product, the practical question is whether a particular decision has a clearly defined answer space. Routing, triage, relevance and yes/no verification do. Open-ended writing does not. Jev is a candidate for the first group, and its value depends on how accurately and cheaply it handles your actual workload, which this guide will keep coming back to.
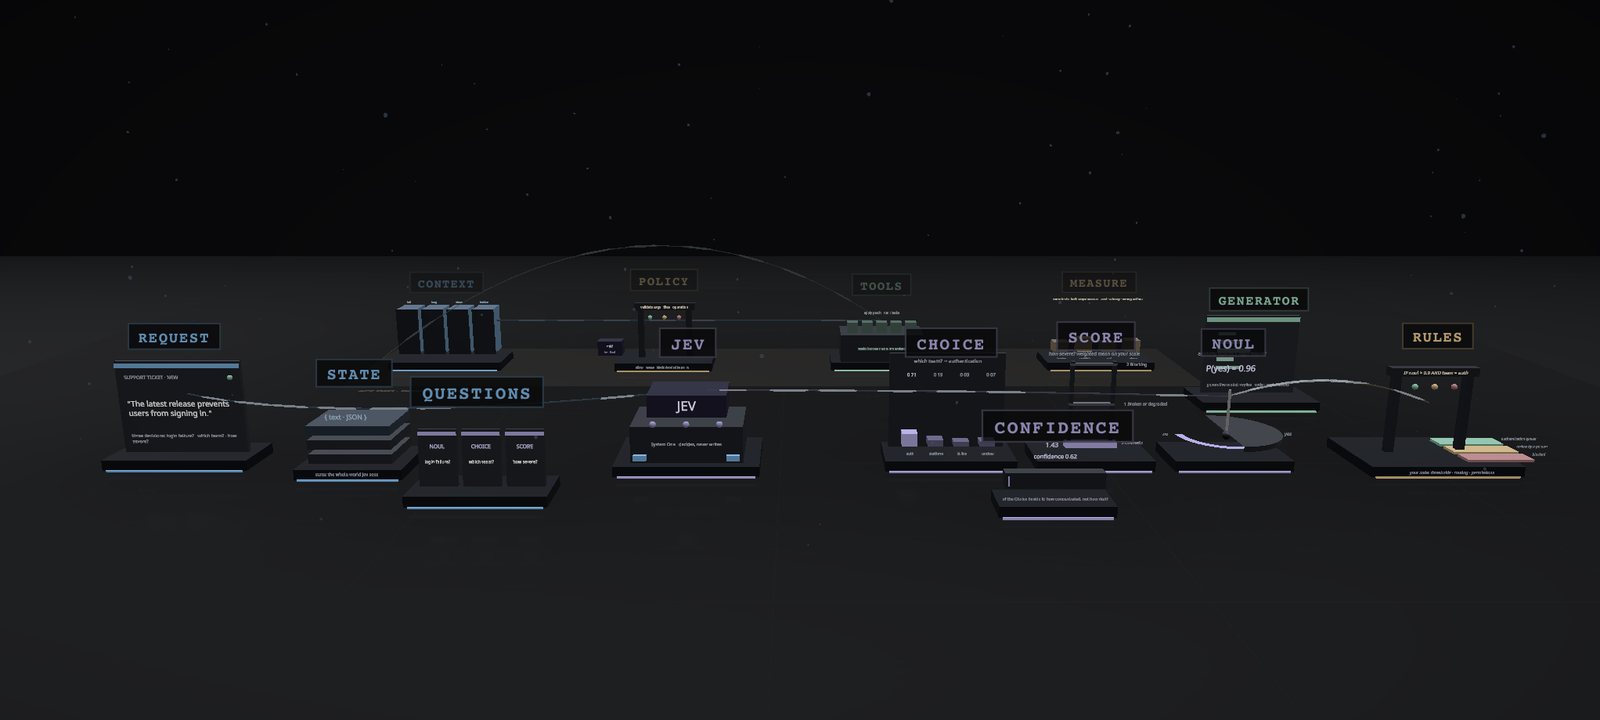
The model below walks one support ticket through the whole thing. On the left, the evidence your code supplies; in the middle, Jev stamping three typed answers; on the right, the rules gate where your own software turns answers into actions, and the generative model at the next desk doing the writing Jev never will. Press play, or click any station.
Loading interactive model…
How to read the model
Size, height and distance represent responsibilities, not speed, intelligence or cost. The Score numbers on the ladder are TypeSafe's documented severity example; the Choice bars and the Noul needle show the shape of an answer and were not produced by Jev. No live request is made.
How does Jev work?
An application sends Jev two essential ingredients: the evidence to evaluate, called the state, and questions that specify what to decide. The request also names the model. State can be text or structured data, such as a record represented in JSON. The response returns one answer per question, and every question in the request is evaluated against the same state, independently.
POST https://api.typesafe.ai/v1/systemone
Authorization: Bearer <API_KEY>

{
  "model": "jev-latest",
  "state": "The latest release prevents users from signing in.",
  "questions": {
    "login_failure": {
      "type": "noul",
      "instructions": "Does the ticket explicitly report a login failure?"
    },
    "team": {
      "type": "choice",
      "instructions": "Which team should investigate?",
      "criteria": {
        "authentication": "Sign-in, sessions, passwords",
        "platform": "Releases, infrastructure, outages",
        "billing": "Charges, invoices, refunds",
        "insufficient_evidence": "The ticket does not say"
      }
    },
    "severity": {
      "type": "score",
      "instructions": "How severe is the reported issue?",
      "criteria": ["Cosmetic", "Broken or degraded", "Blocking"]
    }
  }
}

// response (illustrative values)
{
  "model": "jev-1.13.0",
  "answers": {
    "login_failure": { "type": "noul", "noul": 0.96 },
    "team": {
      "type": "choice",
      "choice": "authentication",
      "probabilities": { "authentication": 0.71, "platform": 0.19, "insufficient_evidence": 0.07, "billing": 0.03 },
      "confidence": 0.62
    },
    "severity": {
      "type": "score",
      "score": 1.43,
      "probabilities": { "0": 0.0, "1": 0.57, "2": 0.43 },
      "legend": { "0": "Cosmetic", "1": "Broken or degraded", "2": "Blocking" },
      "confidence": 0.35
    }
  },
  "usage": { "input_tokens": 118, "output_tokens": 0 }
}Consider the ticket that says "The latest release prevents users from signing in." The application asks whether the ticket explicitly reports a login failure, which team should investigate from a list of teams with clear descriptions of their responsibilities, and how severe the issue is on a scale it defined.
The application then consumes those answers and applies its own rules. A routing decision may determine which queue receives the ticket. It does not, by itself, authorize a production change; that authority lives in a permission check written in ordinary code.
Jev can also support coding agents. It can contribute decisions about which context is relevant or whether a proposed action is permitted while a coding model generates the patch and ordinary tools run the checks. The surrounding software, the harness, still manages retrieval, execution and observations. TypeSafe is explicit that Jev is not a drop-in replacement for the model behind a coding agent.
What do Choice, Score and Noul return?
Jev's three question types answer different kinds of question, and each returns a different shape. The three cards below are the whole vocabulary.
Choice
A Choice is a Jev question that picks one option from a set the application declares, and returns the chosen option, a probability for every option, and a confidence value.
The request names each option and describes it. The response holds choice (the highest-probability option), probabilities (summing to 1 across the declared options) and confidence, a 0 to 1 statistic computed from how concentrated the distribution is. Because the application writes the options, a Choice cannot invent one, which is also why a good option set includes a place for genuine ambiguity such as "insufficient evidence".
- Analogy
- A ballot count that reports every candidate's share, not just the winner.
- Example
- "Which team should handle this ticket?" with returns, shipping and billing as options; TypeSafe's documented example returned returns with probability 1.0.
- Where it sits in an application
- Routing and classification: which queue, which tool, which intent label, which workflow.
Score
A Score is a Jev question that rates the state on an ordered scale the application defines, returning a probability for each level and the probability-weighted position on that scale.
The request supplies levels as an ordered array of descriptions from low to high. The response holds probabilities keyed by level number, score (the sum of each level times its probability), a legend mapping numbers back to descriptions, and confidence. With levels 0, 1 and 2, TypeSafe's documented severity example is 0 x 0.0 + 1 x 0.57 + 2 x 0.43 = 1.43. That number is a position on the scale you wrote; it is not a percentage and not the probability of being correct.
- Analogy
- A thermometer whose markings you wrote yourself. The reading only means what your scale says.
- Example
- "How severe is the reported issue?" on Cosmetic, Broken or degraded, Blocking; 1.43 sits between the second and third rung.
- Where it sits in an application
- Ranking and prioritizing: relevance of a passage, urgency of a message, risk of an action, quality of a draft.
Noul
aka yes/no question · boolean questionA Noul is TypeSafe's name for a yes/no question whose answer is a single probability, between 0 and 1, that the answer is yes.
The request holds instructions and an optional criteria object clarifying what true and false mean. The response holds one field, noul. A value near 1 is a strong yes, near 0 a strong no, and near 0.5 means the model gives both similar weight. There is no separate confidence field, because a two-outcome distribution is fully described by that one number.
- Analogy
- A gauge with one needle. Where it points is the whole answer.
- Example
- "Is the customer asking for a human agent?" on "Can I please just talk to a real person?"; TypeSafe's documented example returned 0.99.
- Where it sits in an application
- Verification and gating: does this passage answer the question, does this command touch credentials, is this claim stated in the document.
A Score needs a defined scale. With levels numbered 0, 1 and 2, a score of 1.43 is a weighted position on that scale. It is not automatically a percentage, and it is not the probability of being correct. Choice and Score also carry a confidence value derived from their probability distribution; a Noul does not, because its single probability already describes both outcomes.
Confidence
Confidence is a 0 to 1 statistic on Choice and Score answers that describes how concentrated the returned probability distribution is; it is not a measure of whether the answer is correct.
One dominant option reads near 1, an even spread reads low. TypeSafe returns the full probabilities as well, so an application can define its own measure. Its guidance is that different actions in the same system deserve different thresholds, set by the consequences of being wrong, and that the right values depend on the domain and the model's measured performance on it. Noul answers carry no confidence field.
- Analogy
- A show of hands. Unanimous tells you the room agrees; it does not tell you the room is right.
- Example
- A Choice that puts 0.71 on one team and spreads the rest reads as moderate confidence; the same team at 1.0 reads as high.
- Where it sits in an application
- The number that decides between act automatically, proceed carefully, and send to a person, once thresholds are validated on real examples.
A confident answer can still be wrong. Useful thresholds for "act automatically", "proceed carefully" and "send to a person" have to be validated on examples from the intended task, and TypeSafe's own guidance is that different actions in the same system deserve different thresholds, set by the consequences of getting each one wrong.
The journey, step by step
The same 12 steps the model plays, as text. The first 10 stations are the decision bench; the last 4 are inside an agent harness, where the same three primitives take on retrieval, gating and measurement jobs.
- 1.A request arrives. A support ticket says: "The latest release prevents users from signing in." Three small decisions have to be made before anyone can help: is it really a login failure, which team owns it, and how severe is it. Follow those three decisions through the bench.
- 2.Your app supplies the state and the questions. The application packages the evidence as state (the ticket text, maybe the account record as JSON) and writes three typed questions with every allowed answer spelled out. Jev sees exactly this and nothing else. It does not search, fetch or remember.
- 3.Jev answers every question in one call. All three questions are evaluated against the same state in a single request, and a typed answer comes back for each. No sentence is generated at any point. That is the whole trick of a System One model, and the reason it can be priced on input tokens alone.
- 4.Choice: which team?. The Choice returns the most probable team and the probability of every team, including "insufficient evidence". In this illustration authentication takes 0.71 of the mass. Because the distribution is not flat, the confidence value is moderate rather than high; your code can read either.
- 5.Score: where on the scale?. The Score spreads probability across the levels you defined and reports the weighted position. TypeSafe's documented severity example lands at 1.43 on a 0 to 2 scale: between "broken or degraded" and "blocking", leaning to the former. It is a position, not a percentage.
- 6.Noul: how likely is yes?. The Noul is one number: the probability that the ticket explicitly reports a login failure. Near 1 says yes with conviction, near 0.5 says the evidence cuts both ways. No confidence field is needed, because that single value already describes the whole yes/no distribution.
- 7.Your code decides what happens next. Answers in hand, ordinary software applies its rules: Noul above the threshold and Choice says authentication, so the ticket goes to the Authentication queue. A routing decision never authorizes a production change; permissions, arithmetic and dates stay in code, where TypeSafe's own limitations page says they belong.
- 8.What Jev is not. The reply to the customer and the fix for the bug come from the generative model at the next desk. Jev does not write, code, chat or browse. Structured-output modes on generative APIs constrain the format of text; neither they nor Jev's typed answers guarantee the values are right.
- 9.Inside an agent: choose what the model sees. The same three primitives can sit inside a coding agent. Here the harness has retrieved the login function, a failure trace, some search hits and the page styles. Jev scores each for relevance; the harness shows the login code in full, summarizes the trace and hides the styles for this turn. Hidden means not in this prompt, never deleted.inside an agent
- 10.Check before acting. The coding model wants to edit the login function. Jev can flag the risk of the proposed action as a Noul. Then code validates the arguments, the files and the operation, and only a permitted tool runs. The flag advises; the policy decides; a high score cannot override a hard deny.inside an agent
- 11.Fix, test, repeat. Tools apply the patch and run the checks. A failing check is new evidence and flows back into the state for the next turn; a passing one goes to review with its diff. The loop is bounded by code, and the test runner, not a model's opinion, establishes whether the checks passed.inside an agent
- 12.Prove the benefit. Run the baseline agent and the Jev-assisted one on the same held-out tasks and measure success, cost per successful task, latency, and wrong allows or blocks. TypeSafe reports large speed and cost gains on its own evals and says they sit at the higher end of real-world results. Independent preprints already show both promise and failure modes. Measure yours.inside an agent
Every station on the bench
| Station | Kind | What happens | Numbers | Source |
|---|---|---|---|---|
| The request | evidence | A support ticket lands. Somebody has to decide what happens to it. Every day a queue fills with tickets like this one: "The latest release prevents users from signing in." Before anyone can fix anything, three small decisions get made, usually by a person skimming: is this really a login failure, which team owns it, and how bad is it. Those three decisions are the kind of work Jev exists for. | Decisions in this example: 3 (a yes/no, a routing choice, a severity) · Text generated by Jev: None | Illustration in this guide |
| State | evidence | The evidence, exactly as your code supplied it. Your application sends Jev the material to judge: the ticket text, and perhaps the customer record as JSON. TypeSafe calls this the state. It is the whole world Jev sees for that request. If a fact is not in the state, Jev cannot use it, and it will not go and fetch it. | Accepted input: string, JSON object, array of text · State + all questions: 64k tokens · State + longest question: 32k tokens | TypeSafe: Models ↗ |
| Questions | evidence | Your code writes the questions and every allowed answer. Alongside the state goes a map of questions, each with a type. For the ticket: a Noul (does it explicitly report a login failure?), a Choice (which team, from a list you define with a description of each), and a Score (how severe, on levels you define). The answer space is yours. Jev cannot invent a fourth team. | Question types: 3: Noul, Choice, Score · Questions per request: one or many, one answer each | TypeSafe: API reference ↗ |
| Jev | decision | A System One model: it decides, it does not write. Jev reads the state, evaluates every question against it in the same call, and returns a typed answer for each. It never produces a sentence. TypeSafe borrows the name from Daniel Kahneman's fast, intuitive System 1, as opposed to the slow, deliberate System 2 that generative models spend their tokens on. | Model ID: jev-1.13.0 (jev-latest) · Input price: $0.042 per million tokens · Output price: free · Vendor-reported latency: 70 to 500 ms end to end | TypeSafe: Introducing System One models and Jev ↗ |
| Choice | decision | Pick one option, and show the probability of every option. For "which team should investigate?", a Choice returns the option with the highest probability and the full distribution over all of them. In the illustration, authentication carries most of the mass, platform some, and insufficient evidence a little. That last option matters: an answer set with room for genuine ambiguity stops uncertainty from being forced into a confident-looking label. | Returns: choice, probabilities, confidence · Illustration: authentication 0.71 · platform 0.19 · insufficient evidence 0.07 · billing 0.03 | TypeSafe: Choice ↗ |
| Score | decision | A position on a scale you defined, as a weighted mean over its levels. For "how severe?", a Score returns a probability for each level and a single number: the probability-weighted position on the scale. TypeSafe's documented severity example puts 0.57 on "broken or degraded" and 0.43 on "blocking", which works out to 1.43 on a 0 to 2 scale. That 1.43 is a position between two rungs. It is not a percentage and not the probability of being right. | Returns: score, probabilities, legend, confidence · Documented example: 0.00 · 0.57 · 0.43 across three levels = 1.43 | TypeSafe: Score ↗ |
| Noul | decision | One number: the probability that the answer is yes. For "does the ticket explicitly report a login failure?", a Noul returns a single value between 0 and 1. Near 1 is a strong yes, near 0 a strong no, near 0.5 an admission that the model gives both similar weight. It is TypeSafe's word for a yes/no question whose answer is a probability, and it is the smallest possible decision. | Returns: noul (probability of yes) · Confidence field: none; the probability is the whole distribution | TypeSafe: Noul ↗ |
| Confidence | decision | How concentrated the probabilities are. Not how right the answer is. Choice and Score answers carry a confidence value derived from their own distribution: one dominant option reads near 1, an even spread reads low. It is a statistic about the answer's shape. A confident answer can still be wrong, which is why the thresholds that decide "act automatically", "proceed carefully" or "send to a person" need to be set on examples from your actual task, not copied from a default. | Carried by: Choice and Score (not Noul) · Range: 0 to 1, from the distribution's spread | TypeSafe: Confidence ↗ |
| Application rules | rule | Your code turns answers into actions. The model never does. The answers come back and ordinary software takes over: a threshold on the Noul, a routing table keyed by the Choice, a severity band from the Score. In the example the ticket goes to the Authentication queue. Nothing about the release itself changes, because a routing decision does not authorize a production change; a permission check in code does. | Decided by code: thresholds, routing, permissions, retries · Decided by Jev: probabilities over your declared answers | TypeSafe: Jev 1.13 jaggedness ↗ |
| Generative model | work | The writer next door: replies, code and explanations come from here. When the workflow needs a reply to the customer, a patch for the bug, or an explanation of anything, that is a generative model's job. Jev does not search the web, does not write, does not hold a conversation, and TypeSafe says so plainly. A system can use both kinds of model; the usual shape is Jev deciding at the joints and a generative model doing the prose in between. | Jev writes: nothing · Documented for generation: not trained for it; slow and ineffective when forced | TypeSafe: Jev with coding agents ↗ |
| Context selectioninside an agent | evidence | Choose what the coding model sees this turn. Inside a coding agent, the harness retrieves candidate material for the task: the login function, part of a failure trace, a few search hits, the project rules. Not all of it should go into this turn's prompt. Jev can score each candidate's relevance so the harness shows the login code in full, a summary of the trace, and hides the unrelated page styles until a later question needs them. | Status: architecture proposal (LangChain, TypeSafe cookbooks) · Jev's part: relevance scores; retrieval stays with the harness | LangChain: Building a harness with Jev ↗ |
| Policy gateinside an agent | rule | A risk judgment, then a real permission check, before any tool runs. The coding model proposes an action: edit the login function, run a command. Jev can answer "does this proposed command touch credentials?" as a Noul. Then deterministic code validates the tool's arguments, the allowed files and the operation, and only a permitted action executes. A high risk score cannot override a hard deny, and a low one cannot grant permission. | Jev's part: advisory risk judgment (Noul or Choice) · Enforcement: schemas, access checks, sandbox, approval | TypeSafe: Function calling ↗ |
| Tools and testsinside an agent | work | Apply the patch, run the checks, feed the result back as evidence. Permitted tools apply the proposed fix and run the relevant checks. If login still fails, the new trace becomes state for the next turn; if the checks pass, the harness prepares the diff and its evidence for review. A passing test is evidence about the cases it tested, not proof that every user path works, so completion is judged against the task's acceptance criteria. | Loop: propose, execute permitted tools, observe, repeat · Stops when: acceptance criteria met, or review requested | Illustration in this guide |
| Measurement benchinside an agent | rule | Run it both ways on the same tasks before believing the diagram. None of this is proven by drawing it. Run a baseline agent and the Jev-assisted agent on the same representative tasks with comparable models, tools and budgets, then ask: did it finish correctly, what did the whole task cost, how long did people wait, and how often did it allow or block the wrong action. TypeSafe's own numbers come from its workflow evals with reference labels averaged from two frontier models; that is useful evidence about that setup, not a guarantee about yours. | Vendor evals: 193.6x faster, 444.6x cheaper, vs consensus reference labels · Independent: arXiv 2609.24052: F1 0.908 vs 2,416 blinded human judgments | TypeSafe: Workflow evals ↗ |
How is Jev different from ChatGPT, Claude and Perplexity?
The comparison involves different kinds of offering. Jev is a specialized model accessed through an API. ChatGPT and Perplexity are assistant products, while Claude refers both to Anthropic's models and to an assistant ecosystem. Putting them in one table is fair only if the table says what each one is for.
| Offering | What it is | Primary role | Output | Example job | Best for | Limit |
|---|---|---|---|---|---|---|
| Jev | A specialized decision model from TypeSafe AI, accessed through an API | Bounded decisions for software | Typed answers with probabilities: Choice, Score, Noul | Classify a query with a defined intent taxonomy | Routing, triage, relevance, verification, gating, at high volume | No text, code or conversation; no web access; typed does not mean correct |
| ChatGPT | OpenAI's general assistant product, with the OpenAI API behind it | Analysis and creation in conversation | Generated text, optionally constrained to a JSON schema | Explain a topic or help develop a research report | Open-ended writing, reasoning and coding help | Slower and costlier per decision; structured output constrains format, not truth |
| Claude | Anthropic's family of generative models and assistant experiences | Generative models and agents | Generated text and code, with documented structured outputs | Analyze evidence, draft a document, generate a patch | Agents that must read, reason and produce work | A different kind of offering; compare specific model versions on the same task, not brands |
| Perplexity | A search-and-synthesis product with its own Sonar models and an Agent API | Search with sources, plus creation tools | Cited answers; the Agent API documents JSON-schema structured outputs | Research a topic and inspect the cited sources | Questions that need the live web and citations | Retrieval is the product; it is not a decision endpoint for your own state |
The distinction is not simply "Jev returns JSON and the others return text." The OpenAI, Anthropic and Perplexity APIs all document structured-output modes. Those features constrain the format of a response; they do not prove that the values in it are correct, and neither does a typed answer from Jev.
Structured output
aka JSON mode · schema-constrained generationStructured output is a generative-model feature that constrains the format of generated text to a schema; it guarantees the shape of a response, not the correctness of its values.
OpenAI, Anthropic and Perplexity document structured-output modes for their APIs. A generative model in that mode still produces text token by token, then conforms it to a JSON schema. Jev differs in kind: it does not generate text at all and returns probabilities over answers the application declared. Neither approach proves that the chosen value is right; a September 2026 preprint on Jev-style models reports a 0% type-error rate alongside large accuracy swings.
- Analogy
- A form that will not let you leave a box blank. It cannot tell you whether what you wrote in the box is true.
- Example
- Asking a generative model to "return JSON with a team field" versus asking Jev a Choice with four teams: the first constrains a sentence, the second returns a distribution.
- Where it sits in an application
- The alternative to Jev for bounded decisions, and one of the baselines a fair pilot compares it against.
For a fair developer comparison, choose specific model versions, give them equivalent evidence and output requirements, and measure the completed task. Comparing Jev's token price with the price of a ChatGPT or Perplexity subscription compares different service bundles and tells you nothing.
An SEO example: labeling keyword intent
Suppose an SEO team has thousands of search queries and wants consistent intent labels before deciding which pages to create or improve. The team can define the labels, write a rubric, and evaluate Jev as one classification option among several. The examples below are an illustrative human labeling scheme, not recorded Jev predictions.
- —"how does fiber internet work" → Informational: asks for an explanation.
- —"fiber vs cable for gaming" → Commercial investigation: compares alternatives for a use case.
- —"buy prepaid SIM card" → Transactional: expresses an intention to purchase.
- —"provider account login" → Navigational: looks for a particular destination.
- —"apple" → Unclear: the query alone does not establish the intended subject.
Leave room for ambiguity
An answer set should have a place for genuine uncertainty. Forcing every query into a commercial category turns "we do not know" into a confident-looking content recommendation, and a Choice will happily put its probability mass wherever the options allow.
A useful pilot compares Jev with the existing rules, an appropriately small classifier, and a structured-output language model. Reviewers label a separate test set, resolve disagreements, and check which categories each system confuses. Inspect the ambiguous cases, not just an overall accuracy score; that is where the systems differ and where the content decisions go wrong.
Query classification is only one possible application. A similar approach could assess whether retrieved passages address a question, or route an SEO request to an existing workflow. Those are proposed uses. Better classification must be demonstrated, and a higher Google ranking does not follow automatically from adopting any particular AI model.
What does Jev cost, and what are its context limits?
On 2026-09-24, TypeSafe's documentation listed Jev 1.13 as jev-1.13.0, priced at $0.042 per million input tokens with free output tokens. It documents text input only, including JSON structures, and no native image, audio or video input.
- —State plus all questions must fit within 64,000 tokens.
- —State plus the single longest question must fit within 32,000 tokens.
- —Both conditions apply at once, which matters when one request carries several questions with long rubrics.
As an illustration, 100,000 calls with 1,000 billed input tokens each would use 100 million input tokens and cost $4.20 at that rate. A real estimate must include the question and rubric tokens, retries, retrieval, any other models, and the surrounding application. This calculation is not a measured production cost.
What are Jev's limitations, and what evidence should you check?
A response can follow the correct format and still select the wrong answer. TypeSafe's own limitations page for Jev 1.13 documents literal reading (it answers the question you wrote, not the one you meant), unreliable arithmetic and counting, dates read as text rather than ordered quantities, trouble with double negatives and indirection, accuracy that falls as irrelevant state grows, no default suspicion of adversarial content, and confusion when instructions contradict the criteria. Keep exact calculations and permission checks in ordinary code.
TypeSafe reports 70 ms to 500 ms end-to-end responses and speed advantages of 40x to 200x on selected decision workloads, with headline evals figures of 193.6x faster and 444.6x cheaper. Its launch post also states the conditions: short, simplified demo inputs chosen to emphasize the difference in sampling, measurements taken from laptops on the US West Coast where the service is hosted, and comparison models run through TypeSafe's own wrapper, which constrains them to emit structured decisions compatible with its API. TypeSafe itself says the headline evals figures sit at the higher end of real-world gains.
The vendor's workflow evals use consensus reference labels averaged from two frontier models rather than independently adjudicated human answers, and they assume the surrounding workflow code is correct. Agreement with that reference is useful evidence about the tested setup; it is not a general correctness guarantee.
Early independent research gives reasons to investigate both the benefits and the failure modes. A September 2026 preprint by Sun and Xu reports that renaming two options from 0/1 to no/yes, with the question, state and rubrics unchanged, changed 70.4 answers per hundred on their open-weights setup and moved AUC from .94 to .23, while the type-error rate stayed at 0%; on the hosted model the same swap moved AUC from .81 to .58. A second preprint by Rafe and Das coded 195,857 Texas crash narratives with a 27-question schema, audited the probabilities against 2,416 blinded human judgments, reports an F1 of 0.908 against human labels, and finds that calibration varies by model and must be audited; recalibrating on labeled data cut calibration error by a factor of 3.3. These are reported findings, not experiments reproduced for this guide.
Documented, proposed, or still needs evidence
- —Documented by TypeSafe: Jev returns Choice, Score and Noul decisions rather than text or code; input-only pricing; the 64k and 32k context conditions; the Jev 1.13 limitations list.
- —Proposed architecture, needs a harness to exist: per-chunk context visibility, conditional instructions, shared retrieval and cache-aware model routing inside coding agents (TypeSafe cookbooks, LangChain).
- —Unsupported: typed outputs guarantee correct decisions. Format validity and decision accuracy are separate properties.
- —Vendor-reported, conditions stated: the 40x to 200x speed and 193.6x / 444.6x evals figures. Useful about that setup; not a measurement of yours.
- —Needs an end-to-end comparison on your tasks: that a Jev-assisted workflow is cheaper, faster or more accurate than your current one. This guide reports no such experiment.
When is Jev worth evaluating?
A recurring task has a bounded answer space, useful evidence is available, and the application can handle uncertainty
→ Evaluate Jev. "Which of these approved workflows fits this request?" is a natural candidate.
You need open-ended writing, code generation, or an unfamiliar problem investigated
→ Start with a generative assistant or coding agent. Add Jev only where a decision inside that work is bounded.
A fragile prompt asks a generative model to "return JSON" for a classification
→ Compare Jev, a small classifier and the structured-output mode on the same labeled test set.
The decision involves exact arithmetic, date comparison or a permission
→ Ordinary code. Jev's own documentation says so.
A system can use both kinds of model, but the additional component should earn its place through measured results. Before adoption, evaluate decision quality, total cost per successful task, response-time variability, and the number of cases that still need human review. Record model versions and repeat the relevant checks whenever the model, the rubric or the input distribution changes.
Frequently asked questions
Who makes Jev?
Jev is developed by TypeSafe AI, which released it on 2026-09-15 and describes it as a System One model for structured, probabilistic decisions. Its founder, Diogo Almeida, wrote the launch post.
Can Jev replace ChatGPT?
No. Jev does not write, code or hold a conversation, so it is not a replacement for ChatGPT's conversational and creative functions. It can be a component in an application that also uses a generative model, for the parts of a task that mean choosing among defined answers.
Does Jev search the web?
No. The documented endpoint evaluates the state your application supplies. Your code has to do the retrieval and pass the relevant evidence in; if a fact is not in the state, Jev cannot use it.
Does Jev eliminate hallucinations?
No. Restricting the answer format prevents invalid outputs, but a permitted option can still be the wrong option for the evidence. TypeSafe documents limitations around arithmetic, dates, indirection, irrelevant context and adversarial content, and a September 2026 preprint shows large accuracy swings with a 0% type-error rate.
Is Jev free?
No. On 2026-09-24 TypeSafe's documentation priced jev-1.13.0 at $0.042 per million input tokens with free output tokens. Free output does not make the service free, and the surrounding application, retrieval and any other models have their own costs. Check TypeSafe's current pricing before estimating a workload.
How fast is Jev?
TypeSafe reports 70 ms to 500 ms end-to-end responses and 40x to 200x speedups over the frontier models it compared, measured on short, simplified demo inputs from the US West Coast, and says its headline evals figures sit at the higher end of real-world gains. Latency on your own workload is something to measure, not assume.
Can I run Jev myself, or is it open weights?
Not as of 2026-09-24: TypeSafe had released neither Jev's weights nor a technical paper on its architecture. It is available through TypeSafe's API and through gateways that list it, including OpenRouter, Vercel AI Gateway and Cloudflare's AI docs. Check each provider's current terms.
Go deeper
Sources & further reading
Endpoint, request and response shapes. Checked 2026-09-24.
jev-1.13.0, $0.042 per million input tokens, free output, 64k and 32k context conditions, text-only input. Checked 2026-09-24.
Option map in, choice plus probabilities plus confidence out.
Ordered levels, probability-weighted score, the 1.43 severity example.
Probability of yes; no separate confidence field.
Derived from the distribution; thresholds depend on consequences and domain.
The definition and the Kahneman reference.
Documented limitations, last reviewed 2026-09-17 per the page.
Not a drop-in replacement for a coding model; where it fits instead.
Bounded tool selection and closed-set arguments.
Launch post, 2026-09-15, Diogo Almeida. Speed and cost claims with their stated conditions.
The 193.6x and 444.6x figures and the consensus reference-label method.
Option-name sensitivity; 0% type errors alongside large accuracy swings. Preprint.
Crash narratives coded with Jev, audited against 2,416 blinded human judgments. Preprint.
Introductory explainer; Jev on Vercel AI Gateway.
Integration guidance.
Routing, relevance and tool-risk gating inside an agent harness, 2026-09-17.
Gateway listing and pricing.
Gateway listing.
Schema-constrained generation on the OpenAI API.
Schema-constrained generation on the Claude API.
What Claude refers to: models and the developer platform.
JSON-schema output control on the Perplexity API.