DeepSeek-R1: AI Reasoning Gets an Upgrade
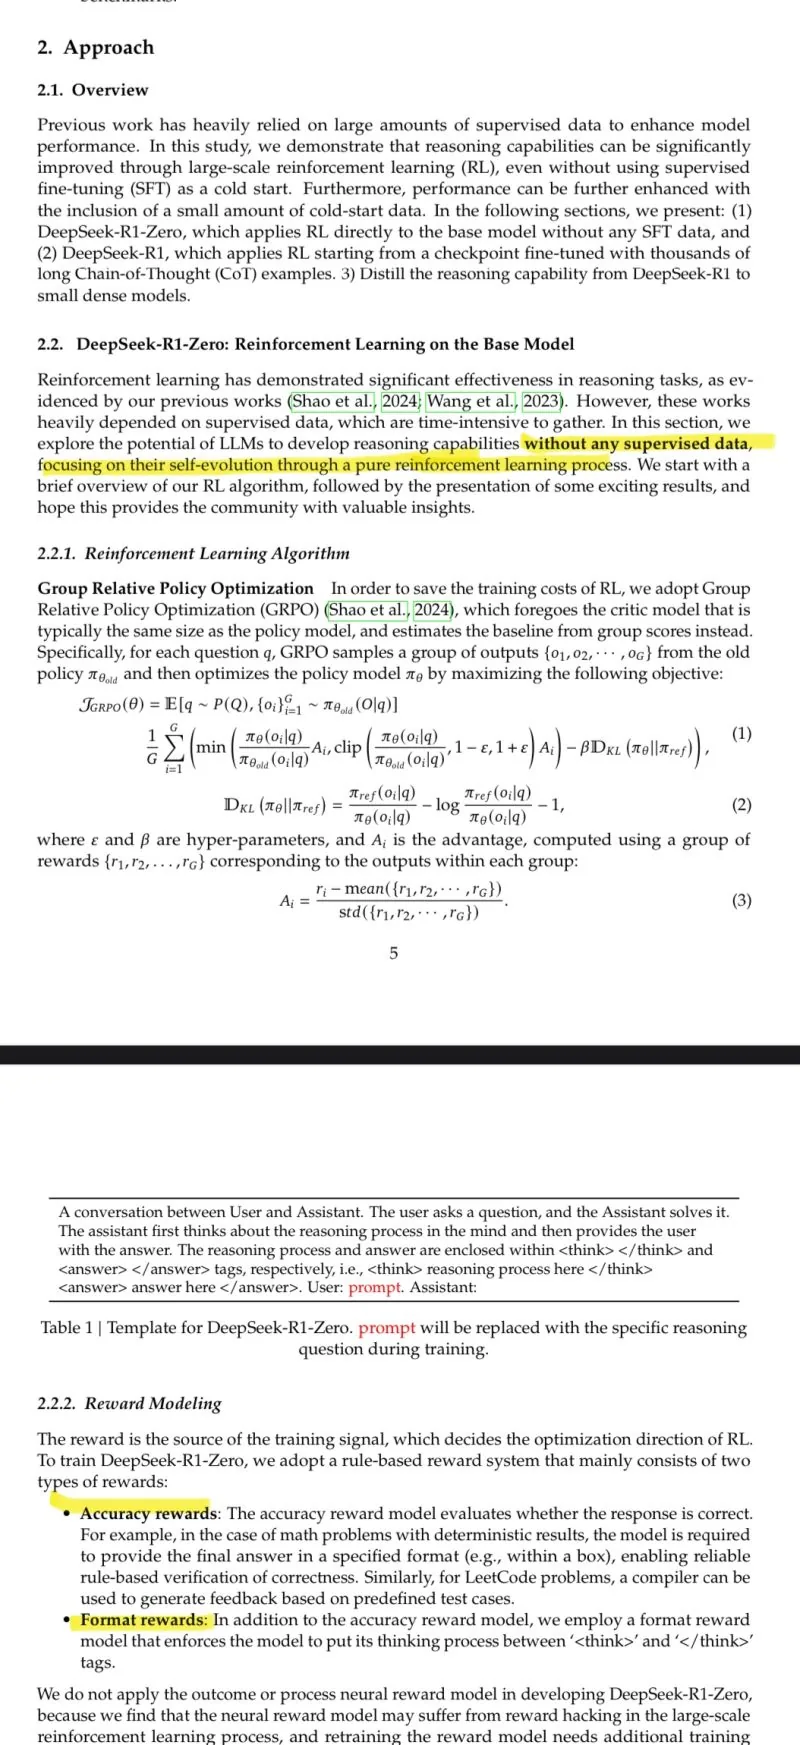
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning Paper: https://lnkd.in/dY54Zkbx
1️⃣ RL > Fine-Tuning? This model learns reasoning purely through RL - no supervised fine-tuning needed.
2️⃣ Smarter AI Self-verification, reflection, and long chains of thought emerge naturally.
3️⃣ Fixing the Flaws A multi-stage training pipeline improves clarity and structure.
4️⃣ Open & Scalable Released models (1.5B-70B) based on Qwen & Llama = better AI for all.
5️⃣ Competing with OpenAI Matches o1-1217 in reasoning - RL may be the future of AI training.
Could RL replace fine-tuning?
.
#AI
#DeepSeekR1
#LLM
#ReinforcementLearning