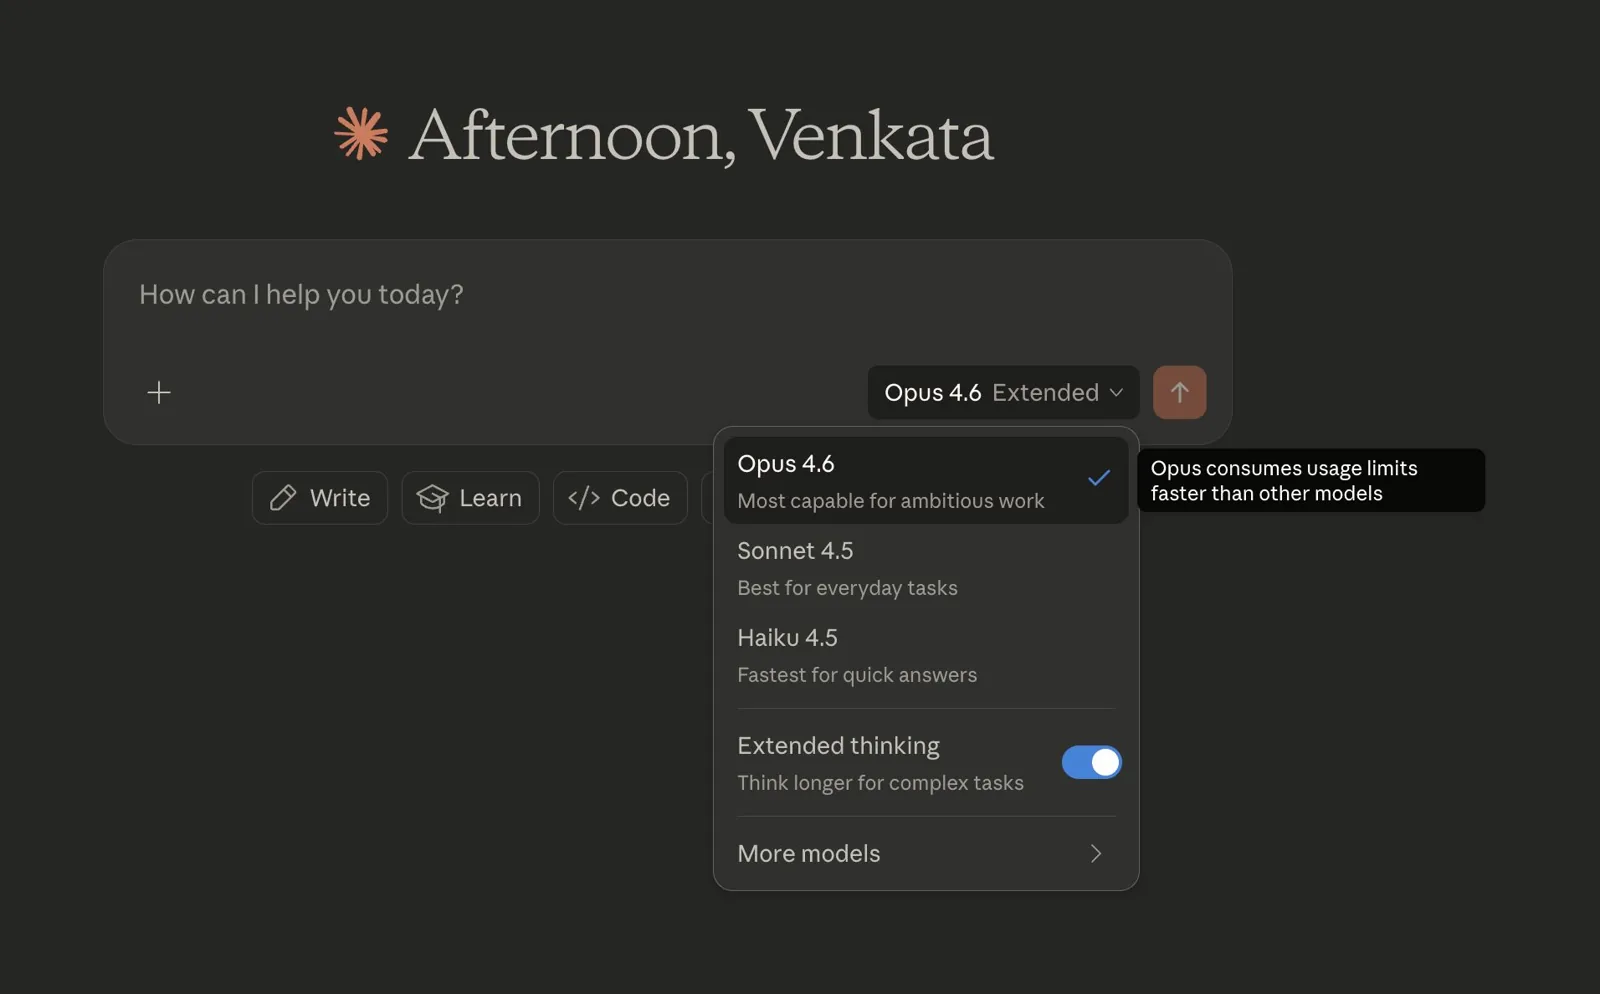
Anthropic just dropped Claude Opus 4.6, their most intelligent model yet. First Opus-class model with a 1M token context window, 128K output tokens, and state-of-the-art scores on agentic coding, reasoning, and knowledge work benchmarks.
Context rot is finally getting solved. Opus 4.6 scores 76% on the 8-needle 1M MRCR v2 benchmark vs. just 18.5% for Sonnet 4.5. That's a qualitative shift in how much context AI can actually use without losing track.
New developer features are game-changers for AI agents - adaptive thinking (model decides when to reason deeply), context compaction (auto-summarizes to avoid hitting limits), agent teams in Claude Code, and granular effort controls (low → max). This is built for long-running autonomous workflows.
The benchmarks speak for themselves: #1 on Terminal-Bench 2.0 (agentic coding), #1 on Humanity's Last Exam (reasoning), #1 on BrowseComp (search), and outperforms GPT-5.2 by ~144 Elo on real-world knowledge work tasks. The frontier just moved.
#Claude #Anthropic
#ClaudeOpus