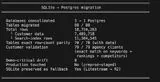
Finished migrating 18.79 million rows across 88 tables from SQLite to Postgres on Omniscite.
When I started building, I picked SQLite because it was the path of least resistance. Single file. No infra. Ship features. I told myself "I'll deal with the database later."
Later arrived. It looked like:
• Writer-lock contention a single fetch job blocking dashboard reads
• Data drift between environments, same query, different answers
• Backup/restore was always one click from being the recovery plan
• Every "small" feature touched dialect-specific SQL that didn't translate cleanly
None of these are SQLite's fault. SQLite did its job. It just isn't the right tool when you have real users, real concurrency, and a product that has to stay up.
Postgres is. So I moved.
What's interesting: the data copy ran in minutes. The hard part was months of dialect-specific assumptions INSERT OR REPLACE, booleans-as-integers,
PRAGMA calls scattered through startup.
The lesson I'd give my past self:
You don't need a "real" database in week one. Ship the MVP. SQLite is fine. But while you're shipping, four things cost nothing and save weeks later:
1. Use an ORM (SQLAlchemy) - covers ~80% of the dialect surface. Plan for the remaining 20% (booleans, PRAGMA, timezone, NUL bytes).
2. Track schema migrations in code from commit 1 (Alembic).
3. Run a Postgres sidecar in CI so dialect drift gets caught at PR time.
4. Never let raw SQLite-specific SQL bleed into business logic. When scale hits, the migration becomes mechanical, not heroic.
Still on my list: WAL archiving + a read replica before this carries prod traffic. Single-instance Postgres is fine for the current load, but not where I want to land. Hope it helps someone avoid the same week-long sprint I just finished.
#ai
#buildinpublic
#databasemigration
#postgresql
#shipping